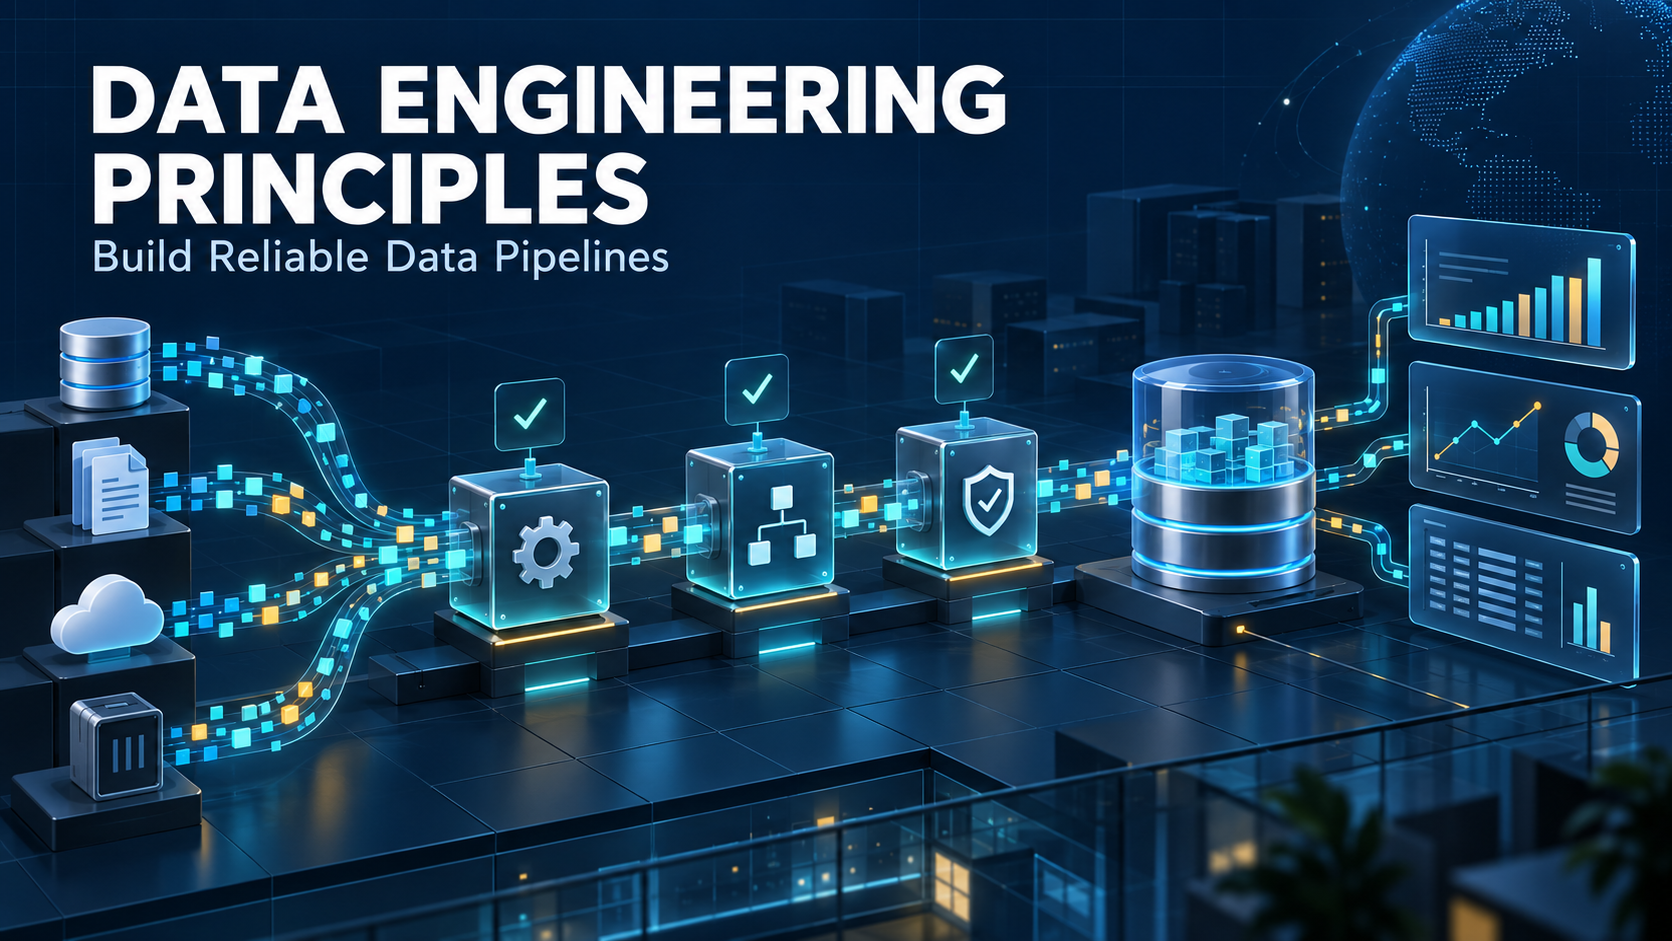
Data engineering principles guide how you collect, organize, transform, and deliver information that people can trust. They connect technical decisions with practical requirements: accurate results, timely delivery, clear ownership, controlled access, and recovery when something goes wrong.
Why do two dashboards report different totals? What happens when yesterday’s import runs twice? Can you explain where a number came from and reproduce it after someone corrects the source?
Those questions matter whether you support a business dashboard, an equipment-monitoring application, or a reporting process that still depends on spreadsheets. Applying Engineering Principles helps you balance reliability, cost, and performance when designing data pipelines around real operating constraints.
Imagine a facility that combines pump readings, maintenance records, and daily operating logs. Each source looks reasonable by itself. Yet the monthly report overstates runtime because repeated readings count twice and two databases use different identifiers for the same pump.
Moving information faster will not resolve either problem. You need consistent definitions, dependable processing, and evidence that the final result represents what actually happened.
What Does Data Engineering Actually Do?
Data engineering builds and maintains the paths between source information and useful outputs. The work includes collecting records, structuring storage, applying business rules, checking results, and keeping delivery dependable.
An analyst might ask why equipment availability declined last month. Data engineers help ensure that the underlying readings, asset identifiers, and maintenance events support a defensible answer.
The data engineering life cycle typically moves through generation, collection, storage, transformation, and delivery. Monitoring, access controls, and ownership run across those activities. They do not belong only at the end.
A data pipeline connects processing steps into a repeatable route. It might retrieve yesterday’s measurements, validate their format, associate them with equipment, calculate daily totals, and publish an approved summary.
Software Engineering Principles help you build data pipelines that are easier to test, maintain, and update when requirements change.
That route needs more than functioning code. Someone must define what counts as downtime, what to do with missing intervals, and when a report becomes ready for use.
The distinction matters because a successful run can still produce an incorrect answer. A task might finish without errors while processing an incomplete file or combining records at the wrong level of detail.
Start by identifying the decision the output supports. If operators need to respond within minutes, a nightly summary may arrive too late. If accounting closes a monthly period, continually refreshing provisional figures might create confusion instead of value.
Useful delivery means providing the right information at the right time, with its limitations visible.
Start With Data Architecture and Clear Requirements
Data architecture describes where information lives, how it moves, and how different systems use it. Keep the arrangement proportionate to the need.
Before selecting a platform, establish the source formats, expected volume, delivery deadline, retention needs, and consequences of failure. Ask who will support the service after the original developer moves on.
A daily operating report may work well with scheduled processing and a relational database. A use case that requires continuous updates may justify streaming. Neither approach automatically offers better value in every situation.
ETL means extract, transform, and load: you reshape information before loading it into the destination. ELT reverses the final two steps, loading first and applying transformations within the destination environment. Microsoft’s overview of ETL and ELT explains this distinction.
Choose based on processing needs, platform capabilities, access restrictions, and cost. Loading source records first can support later reprocessing, but it also requires appropriate controls for any sensitive fields you retain. Electrical Engineering Principles become especially useful when your pipelines handle sensor data, where signal noise and sampling choices affect the information you collect.
Define service expectations in terms people understand. “The report will include complete prior-day readings by 7 a.m.” says more than “the job runs overnight.” Add a response for incomplete delivery: hold publication, show a warning, or supply a clearly identified partial result.
Document the boundaries between producers and consumers. A source agreement should describe identifiers, units, field meanings, expected arrival times, and how the producer will communicate revisions.
These core principles prevent an expensive platform from becoming a complicated route to an ambiguous answer.
Build Reliable Ingestion and Preserve Source Records
Data ingestion should establish what arrived, where it came from, and whether the receiving process captured it completely.
For each delivery, retain useful metadata such as the source identifier, receipt time, file or batch identifier, and processing status. Where appropriate, compare expected and received record counts or use a checksum to detect file alteration.
Keep raw records available for an intentional retention period when permissions and policy allow. If a conversion rule later proves wrong, the original input can help you recalculate the result without asking the source to recreate its history.
Preservation does not mean keeping everything forever. Limit access, exclude unnecessary sensitive fields, and apply retention and deletion rules across relevant copies.
Track event time separately from arrival time. A reading recorded at 11:58 p.m. but received at 12:05 a.m. belongs to different days depending on which timestamp you use. Daily totals need an explicit rule.
Incremental collection introduces another question: how will you detect corrections to older records? Reading only newly created rows may miss an update to last week’s event. Depending on the source, you may need modification timestamps, change capture, or a deliberate lookback window.
A lookback window also needs duplicate handling. Re-reading three days should not add three days of measurements again.
Finally, define what happens when a source adds, removes, or renames a field. Compatible additions may require no interruption. A revised unit or missing identifier may justify stopping affected processing until someone resolves the discrepancy.
Model Business Entities Before Writing Transformations
To model business entities, first identify the real things your records describe: customers, assets, transactions, locations, or events. Then define what one row represents.
That level of detail is the table’s grain. One row might represent a pump reading, a maintenance work order, or a daily asset summary. Mixing those grains without a clear rule invites misleading totals.
Suppose one pump has 24 hourly readings and three work orders during a day. Joining both tables only on pump identifier and date creates 72 rows. Summing the joined readings can triple a quantity even though the query runs successfully.
Aggregate each source to a compatible grain before joining or use a relationship that preserves the intended meaning. Check the number of matching records on each side.
Identifiers deserve equal attention. Equipment names can vary across departments, and someone may rename an asset. Use stable keys and maintain an explicit mapping between source identifiers.
Data transformation also needs documented treatment of units, time zones, null values, and corrections. A missing reading does not automatically mean zero flow. Replacing it with zero silently changes the meaning of the result.
Historical reporting requires another decision. If a pump moves between facilities, should last year’s output follow its current location or the location at the time? Preserve effective dates when the question requires historical context.
Keep those business rules in a maintained, reviewable location. Repeating slightly different calculations in several dashboards makes disagreements almost inevitable.
Aggregation deserves its own check. Suppose a pump runs for nine hours during a ten-hour scheduled period on Monday and one hour during a two-hour scheduled period on Tuesday. The daily availability figures are 90 percent and 50 percent.
Averaging those percentages gives 70 percent. Combining the operating hours and scheduled hours gives 10 divided by 12, or about 83.3 percent. Those answers describe different summaries. If the report intends to show availability across all scheduled hours, use the combined numerator and denominator.
Preserve the quantities behind a percentage so later summaries can calculate the intended measure. A dashboard cannot recover that detail from a rounded percentage alone.
Start with the definition. Write the SQL after you know what the answer should mean.
Make Data Quality Measurable
Data quality depends on fitness for a particular use. A daily summary and an operational alarm may require different levels of completeness and timeliness.
Turn expectations into checks that someone can act on:
- Completeness: Did the expected records and required fields arrive?
- Uniqueness: Does each event appear only as often as the model permits?
- Validity: Do values match the expected format, range, and unit?
- Consistency: Do related records follow the same definitions and relationships?
- Timeliness: Does the latest available information meet the delivery requirement?
- Accuracy: Does the result agree with an appropriate independent reference?
A value can pass a range check and still be wrong. A sensor reporting a constant, plausible temperature may have stopped updating. Examine behavior as well as individual values.
Tools can automate parts of this work. For example, dbt’s data-test documentation describes checks for uniqueness, null values, accepted values, and relationships. The business still needs to supply meaningful expectations.
At the facility, you might compare calculated daily throughput with an independently maintained totalizer, accounting for reset behavior and measurement uncertainty. A meaningful difference triggers investigation; it does not automatically identify which source is wrong.
Set a response for each check. Some failures should block publication. Others may justify a warning or isolation of affected records. Keep rejected information available for authorized investigation instead of silently dropping it.
Assign an owner and include enough context to diagnose the issue. An alert saying “validation failed” creates work. An alert identifying the affected asset, time interval, and failed rule helps someone act.
Design for Retries, Backfills, and Recovery
Assume that a task will eventually stop halfway through its work. The important question is whether you can restart it without corrupting the result.
Idempotency means repeating an operation with the same logical inputs does not create an additional unintended effect. For a daily import, retrying should not duplicate yesterday’s records.
Use stable event keys, controlled replacement of a time partition, or appropriate update-and-insert logic. The correct method depends on whether the source supplies new events, revised records, or complete snapshots.
Apache Airflow’s task-design recommendations emphasize consistent results on retries and processing specific input intervals rather than whichever records happen to be newest.
A backfill recalculates an earlier period. It should use a defined input scope and an identifiable version of the transformation logic. Otherwise, two runs labeled “January” may quietly represent different assumptions.
For safe publication, consider writing results to a staging location, checking them, and then exposing the completed output. Readers should not unknowingly query a half-written report.
Orchestration coordinates dependencies and execution. It can ensure that a summary waits for its inputs, but it cannot independently prove those inputs are complete or correct.
Monitor outcomes alongside task status. A green scheduler dashboard does not establish that the published report contains yesterday’s measurements. Track freshness, record counts, failed checks, and the time since the last complete delivery.
Distinguish temporary failures from persistent defects. A brief connection interruption may justify a limited retry. An invalid field mapping will usually fail again until someone corrects it. Repeating that task indefinitely consumes resources and delays a useful diagnosis.
Also decide how historical corrections reach consumers. Replacing last month’s summary may be appropriate, but downstream exports or cached reports could retain the earlier values. Identify affected outputs, notify their owners when necessary, and preserve an audit trail explaining the revision.
Recovery succeeds when the people using the result receive a consistent, understandable version, not merely when the processing job turns green again.
Test recovery before an incident. Interrupt a sample run, repeat it, and compare the result with a clean execution. That exercise can reveal weaknesses that an uninterrupted demonstration never exposes.
Treat Data Management as Part of the Product
Data management includes ownership, access, documentation, retention, and the rules that make a dataset usable over time. Treat those responsibilities as part of delivery.
Every important output needs someone who can explain its meaning and coordinate corrections. Technical ownership and business ownership may belong to different people, but the responsibilities should be clear.
Document lineage: where a figure originated and which processing steps produced it. When a maintenance supervisor questions a runtime total, you should be able to trace it to the contributing records and calculation version.
Grant access according to the work a person or service needs to perform. A reporting account may need approved summaries without needing credentials for operational equipment or unrestricted access to source tables.
Keep secrets out of scripts, shared spreadsheets, and diagnostic logs. Review exports and temporary files too; protections on the main database do not automatically cover those copies.
Cost also deserves an owner. Repeatedly scanning years of history for a one-day report wastes resources. Partitioning, selective queries, and suitable incremental processing can reduce unnecessary work, depending on the platform and access pattern.
Measure performance before adding complexity. A slow query may reflect an unsuitable join or missing filter rather than inadequate hardware.
Good data engineering best practices connect all these decisions. A dependable output has a defined purpose, understandable rules, appropriate access, and a support process that survives staff changes.
Build Skills Through a Practical Learning Roadmap
An effective data engineering roadmap starts with a small, complete example rather than a long list of platforms.
Learn SQL well enough to understand joins, aggregation, window functions, and null behavior. Practice explaining why a query returns a particular number of rows.
Add a programming language for collection, validation, and automation. Use version control from the beginning so you can review changes and reproduce earlier behavior.
Next, build two connected datasets. Equipment readings and maintenance events work well because they force you to handle identifiers, time, and differing grains.
Load a small sample, calculate a daily summary, and compare it with an answer you can verify manually. Then add duplicate events, delayed arrivals, missing identifiers, and a corrected historical record.
Make the workflows repeatable. Run the same input twice and confirm that totals remain correct. Reprocess an earlier date and record which assumptions the revised output uses.
Books and courses can explain the broader concepts, but choose material that includes modeling, recovery, testing, and operations. A tutorial that ends when the first import succeeds leaves much of the job unexplored.
If you download a fundamentals reference PDF, use an authorized source and check its publication date. Fundamental principles remain useful even when tool interfaces evolve, but installation instructions and service capabilities can become outdated.
A developing engineer benefits from being able to explain one dependable implementation in depth. That demonstrates more than naming a dozen tools without understanding their failure modes.
Frequently Asked Questions About Data Engineering
What are the four pillars of data engineering?
There is no universally standardized four-pillar list. A practical grouping is collection, storage and modeling, transformation and delivery, and trustworthy operation. Quality checks, governance, and access controls run across all four.
Use the grouping to find gaps. If a solution collects records successfully but nobody owns corrections or recovery, it still needs operational work.
Will ETL be replaced by AI?
AI can assist with writing transformations, proposing mappings, and explaining unfamiliar queries. That does not remove the need to extract, prepare, and deliver information or establish what the results mean.
The extent of future automation remains uncertain. A useful present-day approach is to verify generated logic against known examples, review access implications, and assign accountability for published results. Treat generated transformations as proposed work that still needs evidence.
What are the top three competencies for a data engineer?
A useful three-part grouping is querying and modeling, programming and integration, and operational problem-solving. Together, they support correct calculations, dependable connections, and recovery when execution fails.
Communication connects all three. Data engineers need to explain assumptions to the people who define the business question, not only to colleagues who maintain the code.
What are the seven principles of software engineering, and how do they apply here?
Different authors use different seven-item lists. A practical framework covers clear requirements, simplicity, focused responsibilities, explicit interfaces, controlled change, verification, and operational feedback.
For data pipelines, those ideas become documented source agreements, reusable processing steps, versioned calculations, automated checks, and meaningful monitoring. Start by making one important report reproducible: identify its inputs, define its rules, and demonstrate that a retry produces the intended result.